1. Start with the use case, not the database
The first mistake is launching a data project without knowing what AI use case it is supposed to support. An internal assistant, a recommendation engine, anomaly detection or forecasting do not require the same data, nor the same level of rigor. The CNIL explicitly notes that its AI guidance applies to the creation and use of databases when they contain personal data, and that GDPR principles remain the starting point.
The right reflex is straightforward: define the use case, the expected outcome, the decisions AI will support, and then the data categories that are truly necessary. NIST’s risk management framework emphasizes a lifecycle approach built around governance, mapping, measurement and risk treatment. In other words, data should not be prepared for “AI in general,” but for a specific system in a specific context.
Practical decision rule: if the use case is not clear enough to explain which data is indispensable, the project is too early. Reducing scope beats building a costly machine that mostly learns how to be expensive.
- State the use case in one business sentence.
- List the decisions AI will influence.
- Identify the minimum required data.
- Exclude anything without demonstrated usefulness.
2. Quality, coverage and bias: three non-negotiable checks
Preparing data is not just about “cleaning” it. It means checking that it is accurate enough, complete enough, consistent enough, current enough and representative enough of the reality the company wants to model. The EU AI Act requires, for high-risk systems, data governance and management practices appropriate to the intended purpose; that logic is useful well beyond the cases strictly covered by law.
First check: quality. Which columns are empty? Which values are impossible? Which duplicates distort volumes? What is the error rate by source? Second check: coverage. Do the data reflect all relevant populations, sites, periods or products, or only the most visible half of the business? Third check: bias. A “clean” history can still be biased if past decisions were themselves unequal or incomplete. NIST recommends integrating risk measurement and documentation into context of use; that applies to data bias as well.
For an SME, the goal is not academic perfection. It is knowing whether a datum is reliable enough to support a business decision. If it is not, you must choose whether to fix it, weight it, complete it or exclude it. The worst compromise is to swallow it and hope the model will magically turn it wise.
- Measure missing values, duplicates and inconsistencies.
- Compare distributions across sources, sites and time periods.
- Look for collection bias and historical bias.
- Document what is corrected, ignored or retained.
3. Rights, lawful basis and minimization: the sorting that prevents trouble
As soon as personal data is involved, AI data preparation also becomes a compliance issue. The CNIL says data protection must be considered from the collection and management of training data onward, with particular attention to purpose limitation, minimization and controlled reuse.
In practice, a company needs to ask four questions: does it have the right to use this data for this specific purpose? is the data really necessary? does the field contain sensitive, indirectly sensitive or overly granular data? do the notices shown to individuals and the contracts with processors cover this use? “We already have the data” is not a legal basis. Classic move: technically possible, legally fragile, commercially awkward.
The European framework also adds a governance logic for training, validation and test datasets, especially for high-risk systems. Even when a company falls outside that strict scope, the discipline is still worthwhile: it reduces rework, disputes, internal blockers and unpleasant audit surprises.
- Check the purpose of use, not just data possession.
- Minimize attributes before training.
- Identify sensitive and quasi-sensitive data.
- Track rights, retention periods and processors.
4. Traceability, security and annotation: turning chaos into an asset
Data useful for AI must be not only correct, but traceable. You need to know where it came from, when it was collected, who changed it, under which rules and in which version. Without that provenance chain, it becomes nearly impossible to explain model drift, reproduce a result or answer an internal control request. NIST places documentation, validation and interpretation at the center of risk management.
Security matters just as much as quality. Training data, labels, preparation scripts, test sets and annotation histories must be protected against unauthorized access, silent changes and leaks. The CNIL has explicitly highlighted security requirements in its recent work on AI system development.
Annotation also needs method. Who annotates? With which guidelines? What is the inter-annotator disagreement rate? What is the process for resolving ambiguous cases? A poorly defined label set produces a model that is very confident and very wrong, which is a particularly expensive combination.
- Version sources, transformations and datasets.
- Secure access to data and labels.
- Define a stable annotation grid.
- Test reproducibility on a sample.
5. A simple decision framework for SMEs
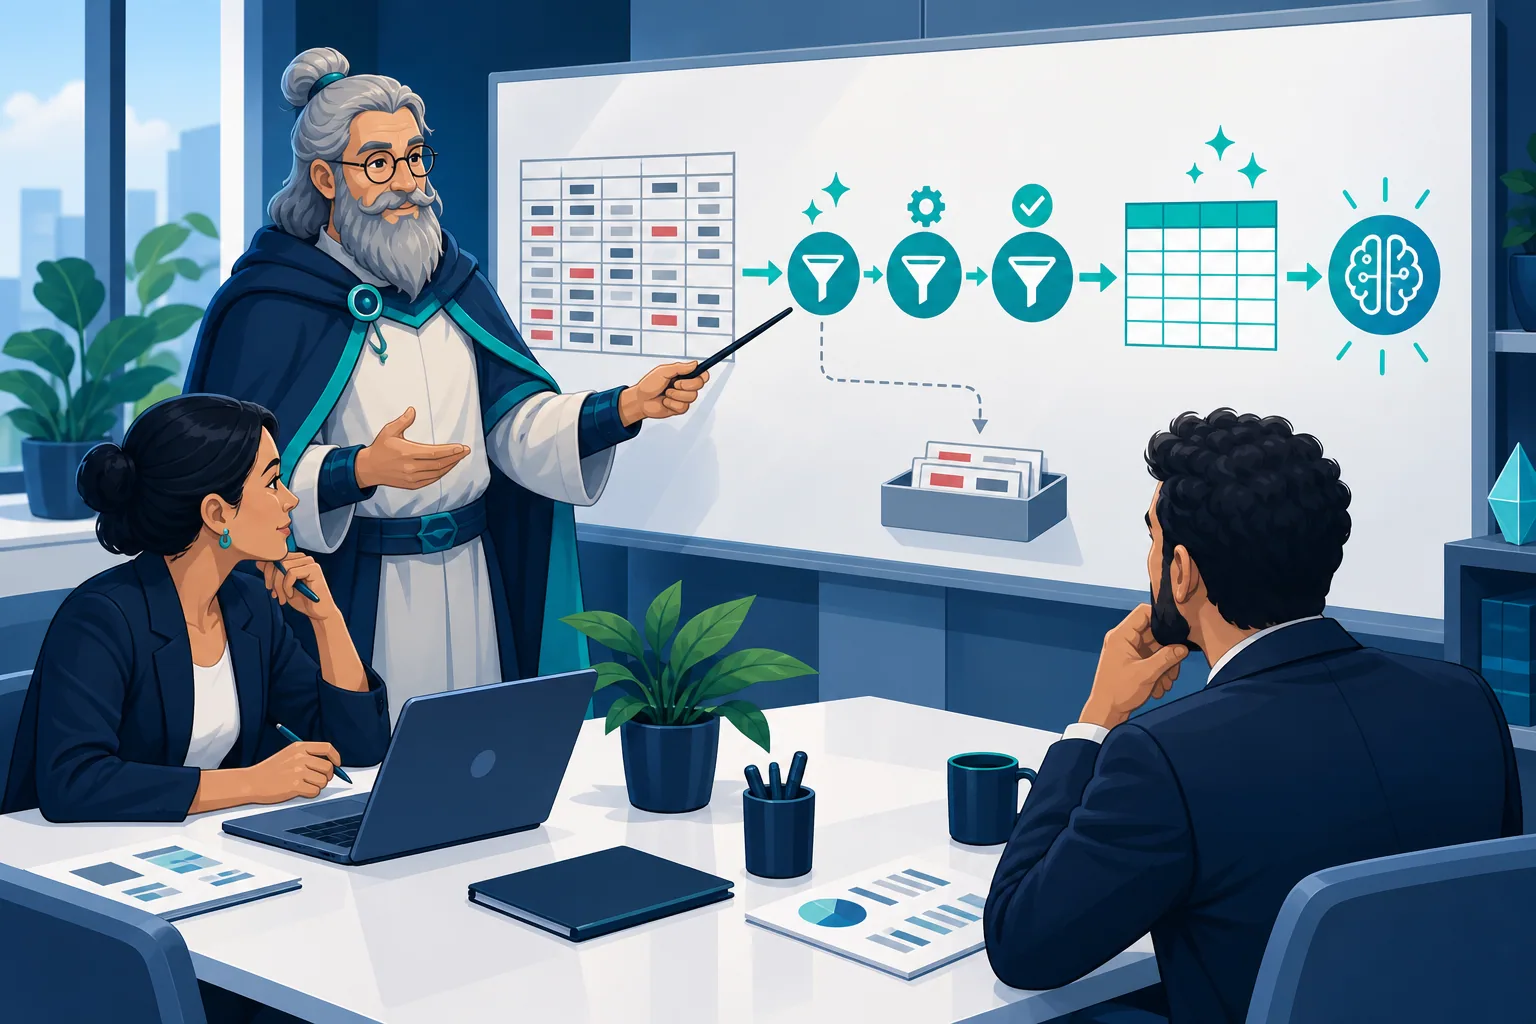
To make quick decisions, use a four-question matrix. 1) Is the data useful for the use case? 2) Is it lawful and proportionate? 3) Is it reliable and representative enough? 4) Is it traceable and secure? If the answer is no to any of these, the data should not enter the AI pipeline as is.
Then classify data into three buckets: ready, to be fixed, and to be excluded. Ready data goes straight into the project; data to be fixed requires a quality, governance or compliance action; data to be excluded should not be used, even if it is tempting because it already exists. This avoids programs that try to use everything and end up using nothing properly.
Business implication: good data preparation reduces time to production, retraining costs and the risk of regulatory surprises. It also improves business trust, because teams accept AI more readily when source data are understandable, controlled and auditable. In AI, speed does not come from well-wrapped chaos; it comes from a database that knows why it exists.
- Ready: usable without major correction.
- To be fixed: useful, but still imperfect.
- To be excluded: too risky, too vague or too costly to make reliable.
- Review the classification whenever scope changes.