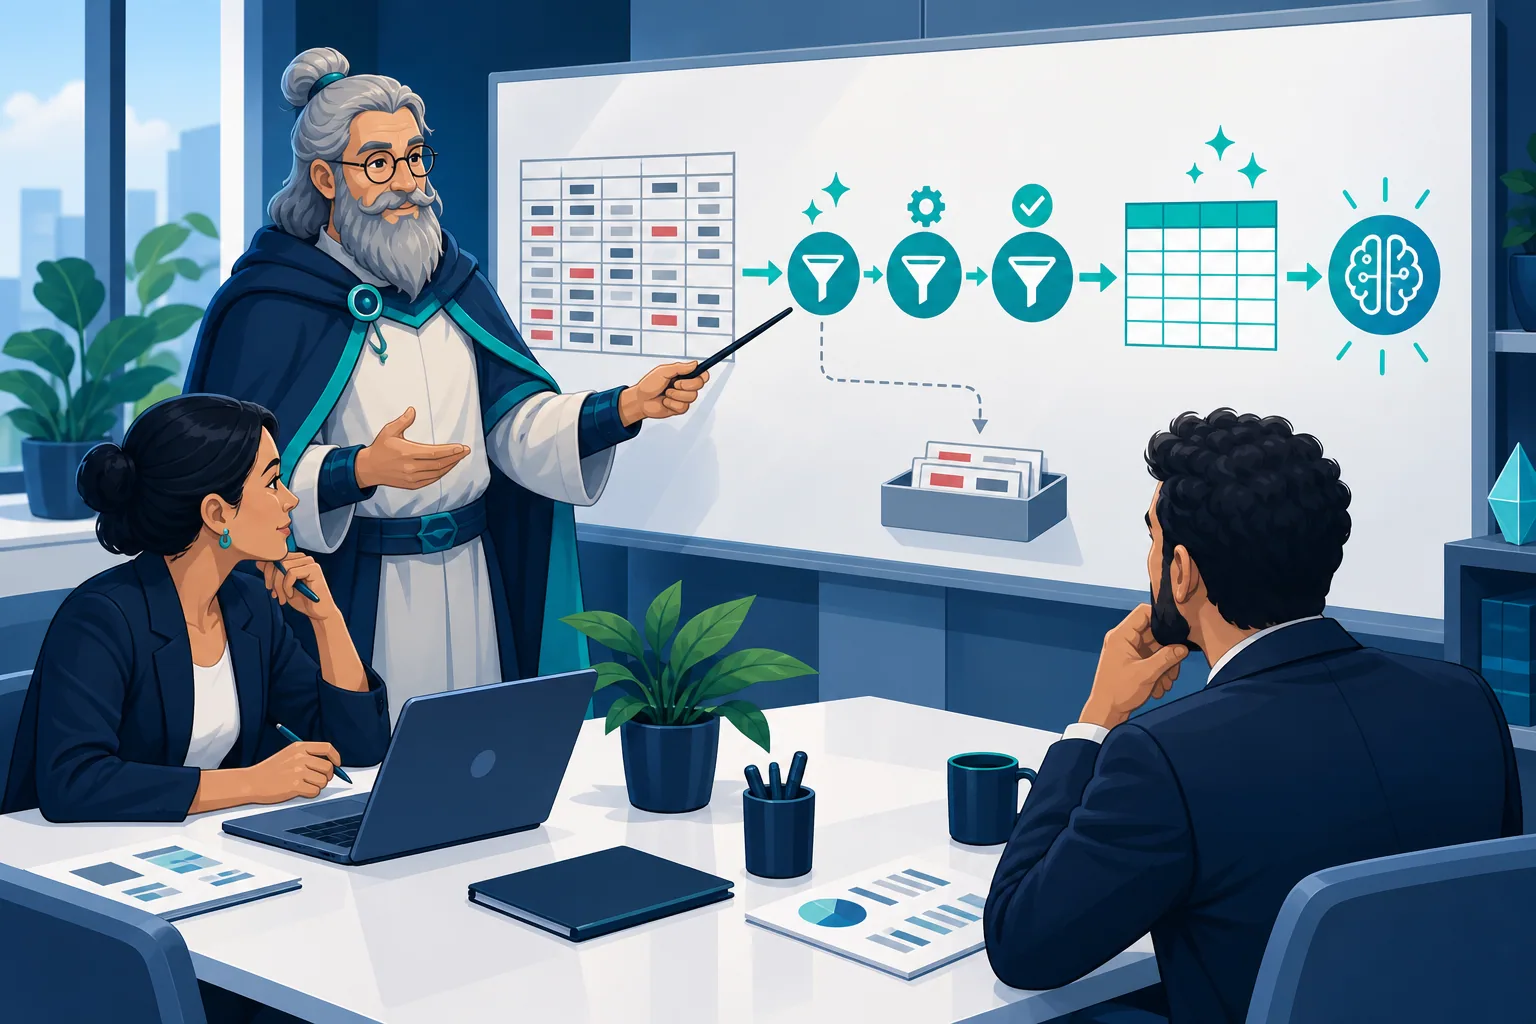
The right question is not “Does the AI work?”
The leadership question is sharper: does this small scope deserve scaling, or only a clean stop? For an SME, an AI pilot is useful only if it supports a concrete decision: continue, correct, or stop. The OECD says risk should be managed across the full AI lifecycle, and CNIL asks organisations to assess the relevant issues in an AI-driven processing project from the design stage.
A well-chosen small scope reduces noise. Test one use case, one data flow, one team, and one business decision. The goal is not a pretty dashboard; it is to see whether AI improves an observable outcome without creating hidden cost, sensitive errors, or excessive supervision. That also aligns with NIST’s approach to testing, evaluation, verification and validation.
- Start with a high-frequency, low-criticality use case.
- Write the decision you expect before the test starts.
- Avoid “everything in one pilot” scopes that make any result endlessly arguable.
Practical method: decide / measure / stop
Here is a simple method that still makes sense if you never buy Datalix. Step 1: write the business hypothesis in one sentence. Example: “For this use case, AI reduces handling time without degrading output quality.” Step 2: choose only three metrics: one value metric, one quality metric, one risk metric. Step 3: define stop criteria before launch: an error threshold, a drift threshold, and a human-load threshold.
Public guidance points the same way. CNIL recommends anticipating compliance, purpose, and security questions as early as possible in the AI project; its 2024 security guide stresses robust testing, access control, and controlled integration. The OECD also notes that AI systems should be managed systematically and assessed in their real-world context.
The winning trio is not “faster, bigger, more AI.” It is: useful for the business, acceptable for risk, sustainable for the team. If one leg is missing, the pilot is probably a polished slide deck in disguise.
- Value: time saved, errors avoided, cases processed.
- Quality: human acceptance rate, sample accuracy, output stability.
- Risk: data incident, drift, validation burden, compliance issue.
Fictional numerical example: an AI assistant for incoming request triage
Fictional example. A small company receives 400 customer requests per month. It runs a 15-day pilot of an AI assistant that suggests a category and draft reply for simple requests. Before launch, the team defines three stop criteria: stop immediately if more than 2 critical misclassifications occur per 100 requests; stop if total time saved is below 20% of agent time; stop if human review takes more than 45 seconds per case on average.
Day 15 result in the fictional example: triage time falls by 28%, but validation time rises on ambiguous cases. After removing complex requests from scope, the performance becomes acceptable. Management conclusion: the pilot does not prove the company should automate all support; it proves a subset of requests can be assisted profitably if humans stay in control. This fits the OECD’s impact-evaluation logic, which asks what changed, for whom, and under what conditions.
The right move is not to “rescue” the pilot at any cost. If the stop criterion is crossed, stop, document, learn. A small, well-explained loss costs less than a large, unjustified expansion.
- Never compare an AI pilot with a friction-free fantasy world.
- Measure hidden supervision load, not only gross savings.
- Keep an error log: that is where the real learning value lives.
Limits you should accept before scaling
A small-scope pilot does not prove scale robustness. It does not validate every use case, every dataset, or every team. CNIL guidance on AI reminds organisations that a system may involve personal-data processing and trigger specific checks; security also has to be tested, not assumed.
Another limit: a good pilot can still hide a future industrial failure. If production data changes, users bypass the tool, or supervision becomes too costly, the original promise deteriorates. That is why explicit stop criteria matter: they prevent learning from being confused with stubbornness.
Finally, some cases are simply not worth piloting. If potential value is low, regulatory risk is high, or the data is too poor to be useful, stopping is not failure; it is disciplined management.
- A pilot is not a substitute for architecture or governance.
- A solid local demo does not guarantee durable operations.
- Stopping early may be the best project outcome.
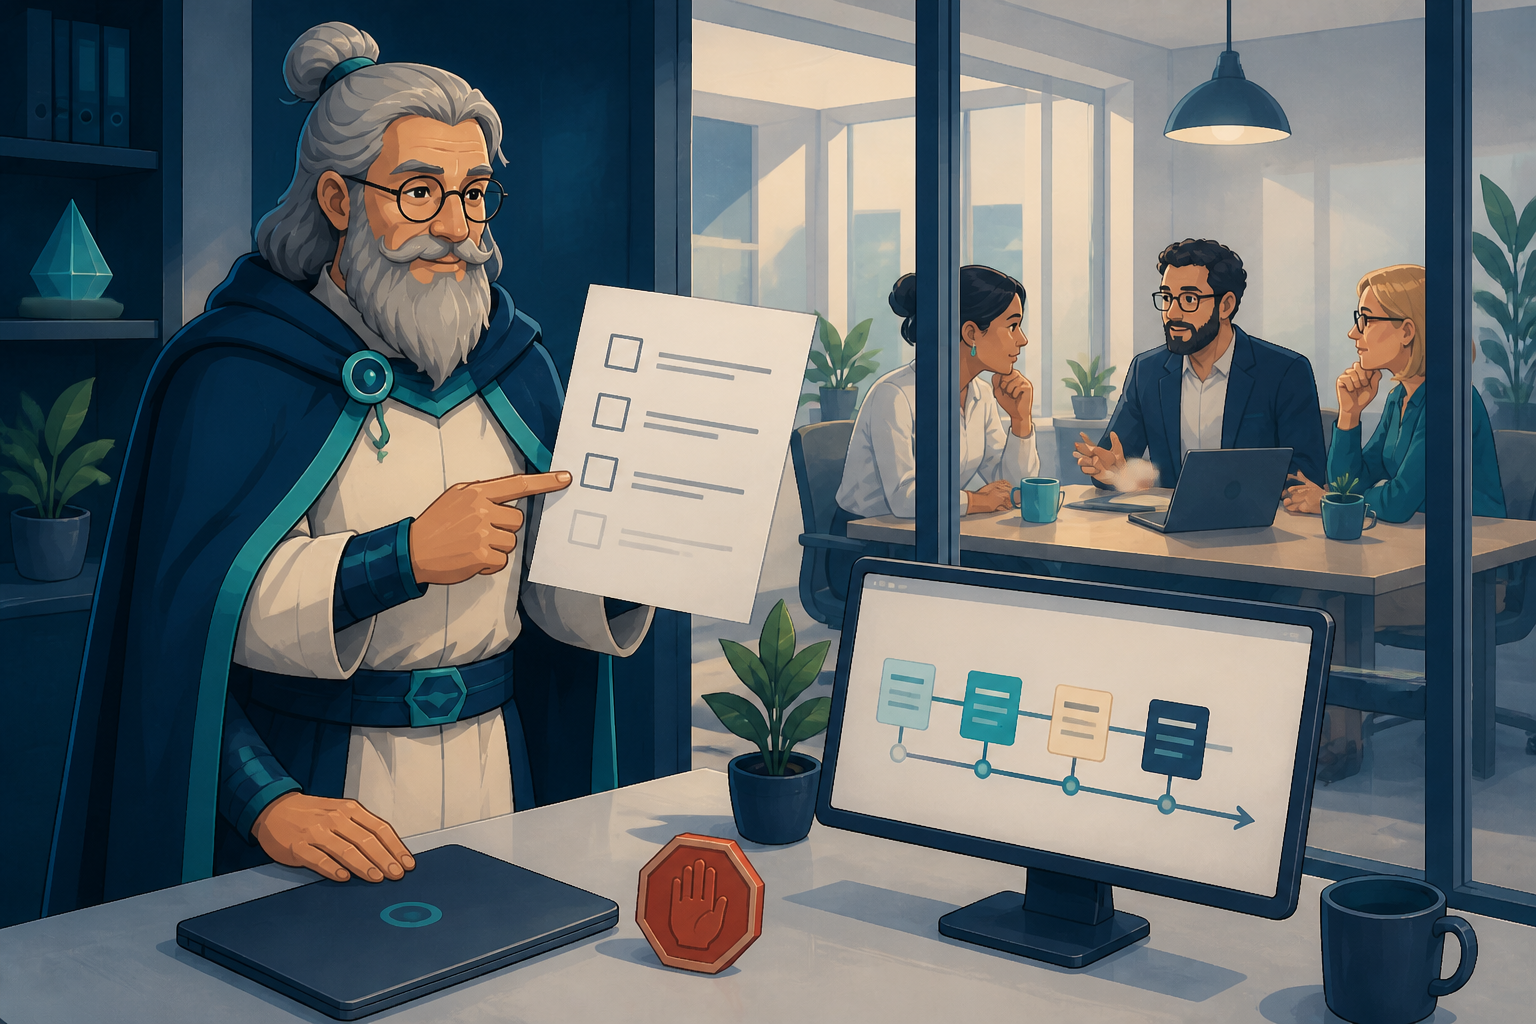
A seven-day action checklist
Day 1: the business sponsor defines the use case and target decision. Day 2: the DPO and security lead validate the data scope and risk points. Day 3: the product or operations owner writes three metrics and three stop criteria. Day 4: the operational lead prepares a sample of real cases. Day 5: the team launches the small-scope test. Day 6: sponsor and operators review failures and hidden costs. Day 7: leadership decides to continue, adjust, or stop.
The observable result is not “the AI works,” but a documented decision: expanded scope, reduced scope, or a documented stop. Unexciting? Yes. Cheaper than a blind rollout? Also yes.
If you keep only one rule, keep this one: an AI project on a small scope succeeds only when its stop criteria are clear enough to make a “no” easy.
- Day 1 — Business sponsor: use case and target decision written.
- Day 2 — DPO / security: permitted data and risks noted.
- Day 3 — Product / ops: metrics and stop rules signed off.
- Day 4 — Operations: real-case sample ready.
- Day 5 — Project team: test launched.
- Day 6 — Sponsor + ops: review of gaps and hidden costs completed.